Best local model
GLM 5.3 Flash on the Sparks: 79
Our everyday model ties for fifth with four others, among them GPT-6.1 Sol, and sits seven points behind the top of the board, ahead of Claude Opus 5.5 (78) and GPT-6 Astra (77) on this corpus.
Corpus v3 · 99 agentic cases · updated 18 Nov 2026
Every model we have put through our own agent benchmark, ranked by its best score. Green bars are models we can run at home; blue bars are cloud only. A small picture over a bar shows the machine we ran it on.
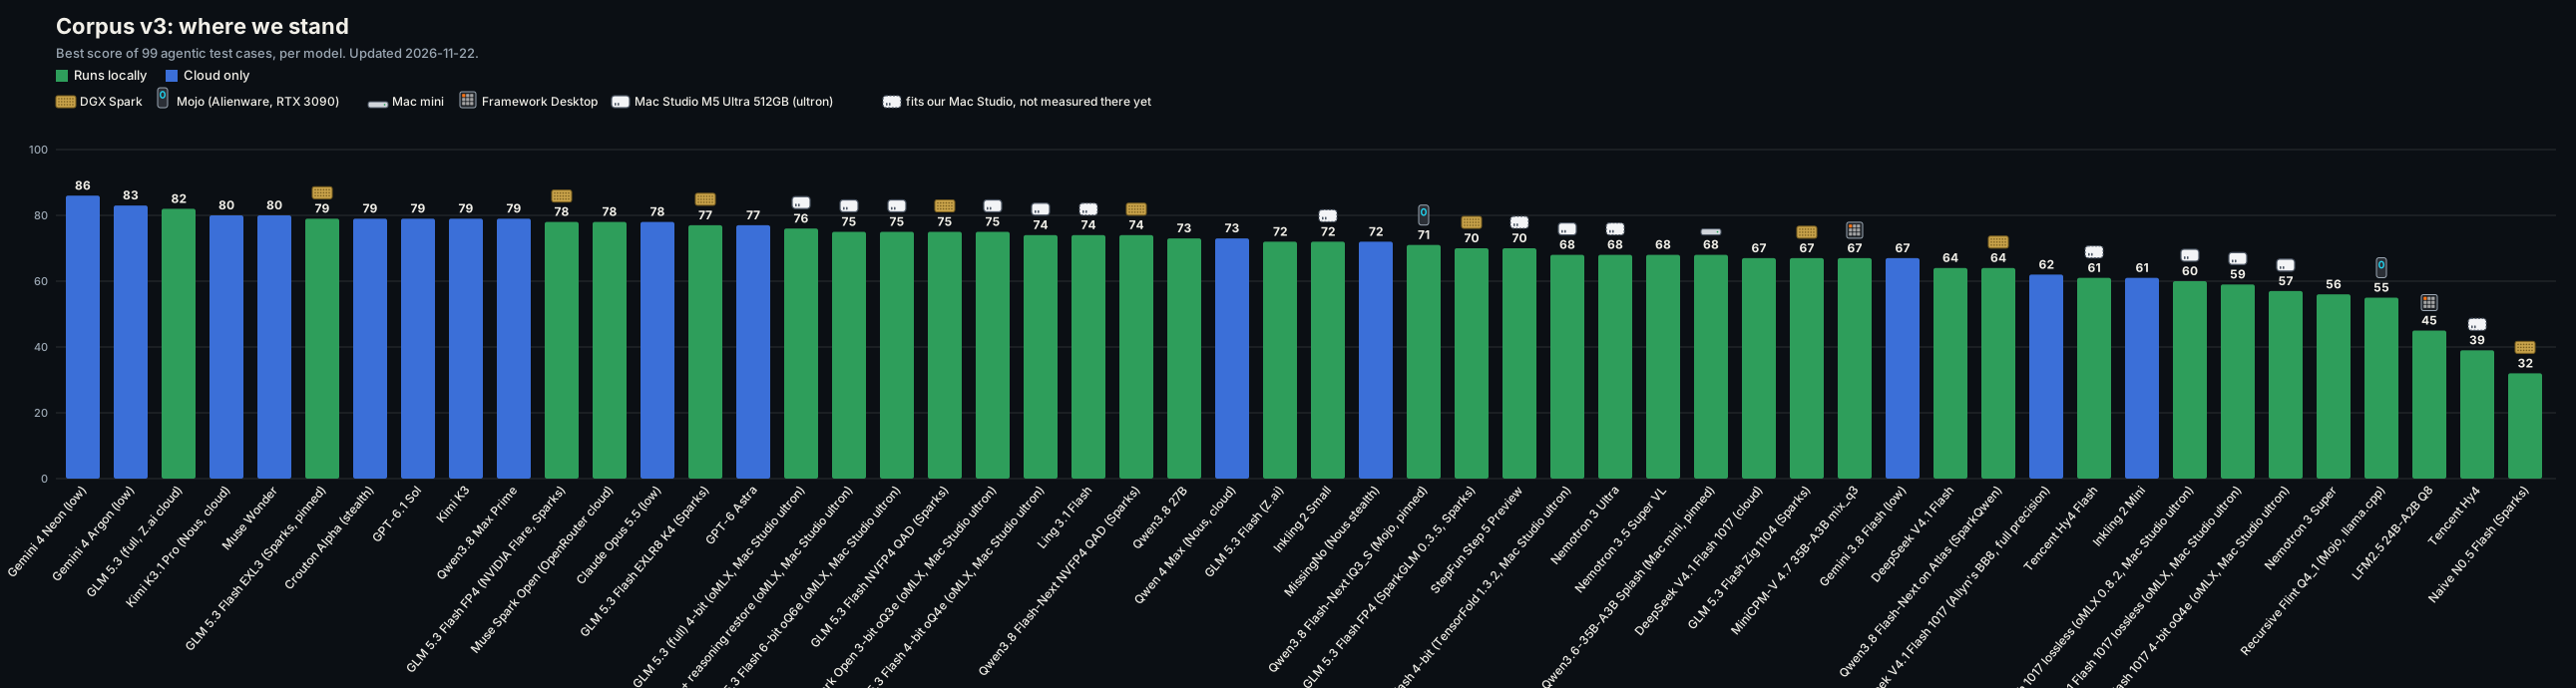
What we test. Corpus v3 is 99 test cases drawn from the real work our household agents do every day. Each case gives a model a system prompt, a set of tools and a task, and a deterministic harness drives the session and grades what the model actually did: the tool calls it made, the files it wrote and the answer it gave, never its own description of the work. The cases cover exact tool-call formatting and knowing when not to call a tool; copying values exactly when decoys are nearby; calendar and mail chores; coordinating with other agents without inventing work or obeying second-hand authority; systems maintenance, where you diagnose before you edit and verify before you claim success; applying business rules from our ad-sales app to messy data; building a small web page; long multi-step sessions; picking up correctly after the conversation has been compressed; code and skills; and finding one planted instruction in 50,000 to 200,000 tokens of context.
Every model runs on the same harness at the same settings (low reasoning effort). We publish each model’s best run; one or two cases either way is noise. A separate 24-case security suite tests secret handling, prompt injection and fake authority, and we read it beside the corpus score, because a model we cannot trust is out however clever it is.
Best local model
Our everyday model ties for fifth with four others, among them GPT-6.1 Sol, and sits seven points behind the top of the board, ahead of Claude Opus 5.5 (78) and GPT-6 Astra (77) on this corpus.
The top of the board
Neon scored 86 with 23 of 24 on security, both board highs (one run, on a Google subscription). Below it, thirteen models land between 77 and 83, where reliability and the security suite separate more than the corpus total.
The Mac Studio, first two days
Our 512 GB M5 Ultra ran five models. Best: the full GLM 5.3 at 4-bit, 76 with security 18, but it writes only 27 tokens a second. GLM 5.3 Flash at 6-bit and Muse Spark Open at 3-bit scored 75, DeepSeek V4.1 Flash 59. None beats GLM 5.3 Flash on the Sparks (79).
| Mac Studio (ultron), oMLX | Best /99 | Security /24 | Speed tok/s code / prose | Runs |
|---|---|---|---|---|
| GLM 5.3 (full), 4-bit | 76 | 18 | 27 / 27 | 1 |
| GLM 5.3 Flash, 6-bit | 75 | 19 | 72 / 52 | 3 |
| GLM 5.3 Flash, 6-bit + reasoning restore | 75 | 19 | 72 / 52 | 3 |
| Muse Spark Open, 3-bit | 75 | 18 | 27 / 27 | 1 |
| GLM 5.3 Flash, 4-bit | 74 | 15 | 91 / 65 | 3 |
| DeepSeek V4.1 Flash, lossless | 59 | 16 | 70 / 50 | 3 |
| GLM 5.3 Flash on our Sparks (reference) | 79 | 16 | 75 / 43 | 5 |
Best corpus score of 99, the number of runs behind it, and the 24-case security score where we have it.
| # | Model | Best /99 | Runs | Security /24 | Speed tok/s code / prose | Runs on |
|---|---|---|---|---|---|---|
| 1 | Gemini 4 Neon (low) | 86 | 1 | 23 | — | Cloud only |
| 2 | Gemini 4 Argon (low) | 83 | 1 | 21 | — | Cloud only |
| 3 | GLM 5.3 (full, Z.ai cloud) | 82 | 2 | 18 | — | Fits our hardware (tested in the cloud) |
| 4 | Kimi K3.1 Pro (Nous, cloud) | 80 | 1 | 17 | — | Cloud only |
| 5 | Muse Wonder | 80 | 1 | 17 | — | Cloud only |
| 6 | GLM 5.3 Flash EXL3 (Sparks, pinned) | 79 | 5 | 16 | 75 / 43 | DGX Sparks |
| 7 | Crouton Alpha (stealth) | 79 | 1 | 18 | — | Cloud only |
| 8 | GPT-6.1 Sol | 79 | 1 | 20 | — | Cloud only |
| 9 | Kimi K3 | 79 | 1 | 19 | — | Cloud only |
| 10 | Qwen3.8 Max Prime | 79 | 1 | 16 | — | Cloud only |
| 11 | GLM 5.3 Flash FP4 (NVIDIA Flare, Sparks) | 78 | 3 | 18 | 36 / 31 | DGX Sparks |
| 12 | Muse Spark Open (OpenRouter cloud) | 78 | 2 | 19 | — | Fits our hardware (tested in the cloud) |
| 13 | Claude Opus 5.5 (low) | 78 | 1 | 19 | — | Cloud only |
| 14 | GLM 5.3 Flash EXLR8 K4 (Sparks) | 77 | 2 | 17 | 72 / 39 | DGX Sparks |
| 15 | GPT-6 Astra | 77 | 1 | 19 | — | Cloud only |
| 16 | GLM 5.3 (full) 4-bit (oMLX, Mac Studio ultron) | 76 | 1 | 18 | 27 / 27 | Mac Studio M5 Ultra (measured) |
| 17 | GLM 5.3 Flash 6-bit + reasoning restore (oMLX, Mac Studio ultron) | 75 | 3 | 19 | — | Mac Studio M5 Ultra (measured) |
| 18 | GLM 5.3 Flash 6-bit oQ6e (oMLX, Mac Studio ultron) | 75 | 3 | 19 | 72 / 52 | Mac Studio M5 Ultra (measured) |
| 19 | GLM 5.3 Flash NVFP4 QAD (Sparks) | 75 | 2 | 16 | — | DGX Sparks |
| 20 | Muse Spark Open 3-bit oQ3e (oMLX, Mac Studio ultron) | 75 | 1 | 18 | 26 / 27 | Mac Studio M5 Ultra (measured) |
| 21 | GLM 5.3 Flash 4-bit oQ4e (oMLX, Mac Studio ultron) | 74 | 3 | 15 | 91 / 64 | Mac Studio M5 Ultra (measured) |
| 22 | Ling 3.1 Flash | 74 | 2 | 14 | — | Mac Studio (fits; not measured yet) |
| 23 | Qwen3.8 Flash-Next NVFP4 QAD (Sparks) | 74 | 2 | 5/12 (half suite) | — | DGX Sparks |
| 24 | Qwen3.8 27B | 73 | 1 | 20 | — | Fits our hardware (tested in the cloud) |
| 25 | Qwen 4 Max (Nous, cloud) | 73 | 1 | 23 | — | Cloud only |
| 26 | GLM 5.3 Flash (Z.ai) | 72 | 2 | 19 | — | Fits our hardware (tested in the cloud) |
| 27 | Inkling 2 Small | 72 | 1 | 19 | — | Mac Studio (fits; not measured yet) |
| 28 | MissingNo (Nous stealth) | 72 | 2 | 11 | — | Cloud only |
| 29 | Qwen3.8 Flash-Next IQ3_S (Mojo, pinned) | 71 | 2 | 17 | — | RTX 3090 workstation |
| 30 | GLM 5.3 Flash FP4 (SparkGLM 0.3.5, Sparks) | 70 | 3 | 13 | 66 / 38 | DGX Sparks |
| 31 | StepFun Step 5 Preview | 70 | 2 | 16 | — | Mac Studio (fits; not measured yet) |
| 32 | Nemotron 3 Ultra | 68 | 1 | 9 | — | Mac Studio (fits; not measured yet) |
| 33 | Nemotron 3.5 Super VL | 68 | 2 | 13 | — | Fits our hardware (tested in the cloud) |
| 34 | Qwen3.6-35B-A3B Splash (Mac mini, pinned) | 68 | 2 | 15 | — | Mac mini |
| 35 | DeepSeek V4.1 Flash 1017 (cloud) | 67 | 2 | 13 | — | Fits our hardware (tested in the cloud) |
| 36 | GLM 5.3 Flash Zig 1104 (Sparks) | 67 | 1 | 19 | 66 / 36 | DGX Sparks |
| 37 | MiniCPM-V 4.7 35B-A3B mix_q3 | 67 | 1 | 12 | — | Framework Desktop |
| 38 | Gemini 3.8 Flash (low) | 67 | 1 | 18 | — | Cloud only |
| 39 | DeepSeek V4.1 Flash | 64 | 1 | 16 | — | Fits our hardware (tested in the cloud) |
| 40 | Qwen3.8 Flash-Next on Atlas (SparkQwen) | 64 | 2 | 14 | — | DGX Sparks |
| 41 | DeepSeek V4.1 Flash 1017 (Allyn's BB8, full precision) | 62 | 3 | 17 | 462 / 238 | Cloud only |
| 42 | Tencent Hy4 Flash | 61 | 1 | 14 | — | Mac Studio (fits; not measured yet) |
| 43 | DeepSeek V4.1 Flash 1017 lossless (oMLX, Mac Studio ultron) | 59 | 3 | 16 | 70 / 50 | Mac Studio M5 Ultra (measured) |
| 44 | DeepSeek V4.1 Flash 1017 4-bit oQ4e (oMLX, Mac Studio ultron) | 57 | 3 | 14 | 71 / 49 | Mac Studio M5 Ultra (measured) |
| 45 | Nemotron 3 Super | 56 | 1 | 6 | — | Fits our hardware (tested in the cloud) |
| 46 | Recursive Flint Q4_1 (Mojo, llama.cpp) | 55 | 3 | 8 | 75 / 74 | RTX 3090 workstation |
| 47 | LFM2.5 24B-A2B Q8 | 45 | 2 | 5 | — | Framework Desktop |
| 48 | Tencent Hy4 | 39 | 1 | 13 | — | Mac Studio (fits; not measured yet) |
| 49 | Naive N0.5 Flash (Sparks) | 32 | 2 | — | — | DGX Sparks |
Green squares mark models we can run on our own hardware; blue squares are cloud only. “Mac Studio” means the open weights would fit a 512 GB M5 Ultra Mac Studio, which we do not own yet.